Research Interests
Our research focuses on processing, annotation, and interpretation of cutting-edge omics datasets to understand human diseases such as cancers. Our approaches include computational/statistical modeling, machine learning, large data integration, and close wet-lab collaboration.
Integrative Omics
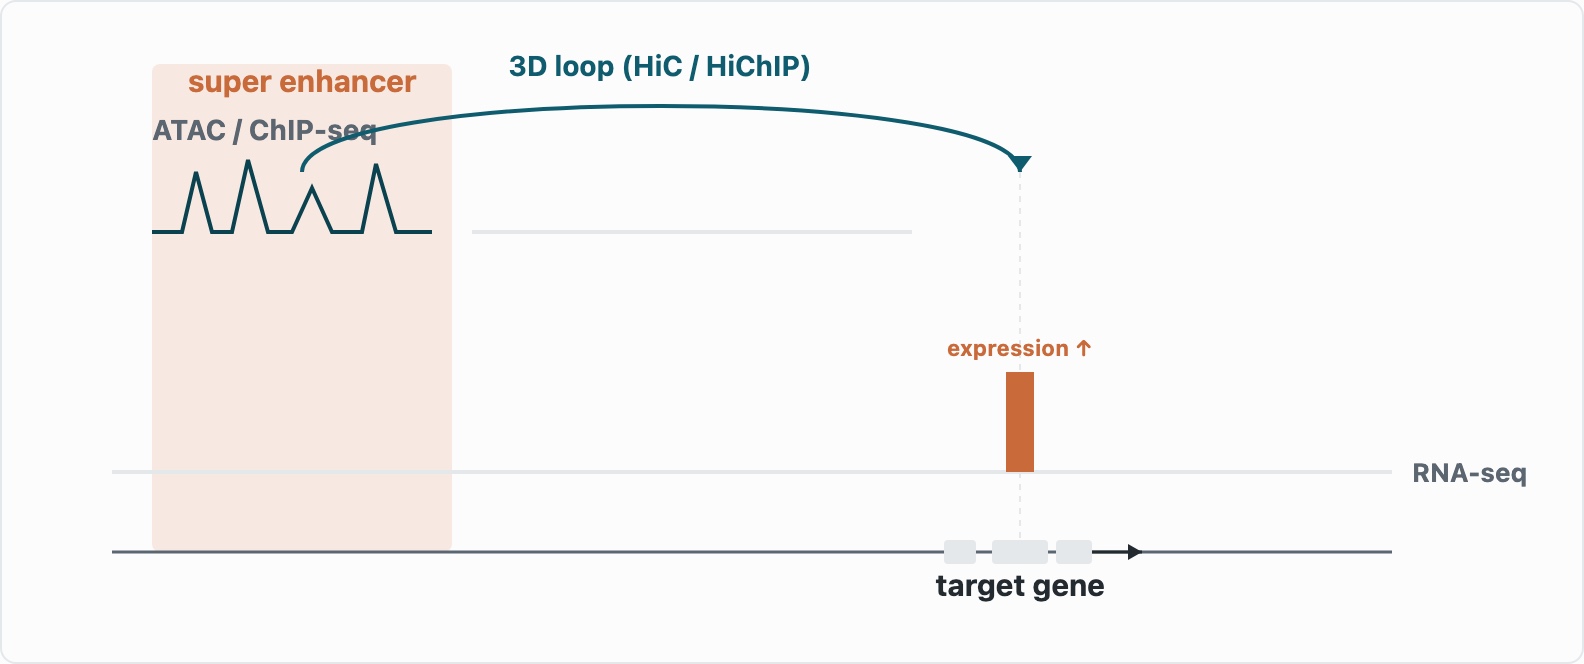
Data accumulation in multi-omics enables us to better interpret gene/protein functions through integrative approaches. Our group develops computational methods to address data integration with: gene expression (RNA-seq, scRNA-seq, spatial transcriptome), chromatin status/accessibility (ChIP-seq, ATAC-seq, scATAC-seq), 3D chromatin looping (HiC & HiChIP), genome editing (CRISPR screens) and protein/metabolite expression (spatial proteomics/MALDI).
- Understanding enhancer function with multi-omics data integration. Key questions to interpret enhancer function include who and how enhancers organize gene regulation. We integrate sequencing assays measuring enhancer acitivities, enhancer-protein binding, gene expression and enhaner-gene interactions to provide quantitative answers to the questions. With well-designed integrative approaches, we uncovered novel insights to understand super enhancer internal organization and their roles in defining cancer identities. By integrating public datasets with in-house validations, we identified critical enhancer regulators in cancers.
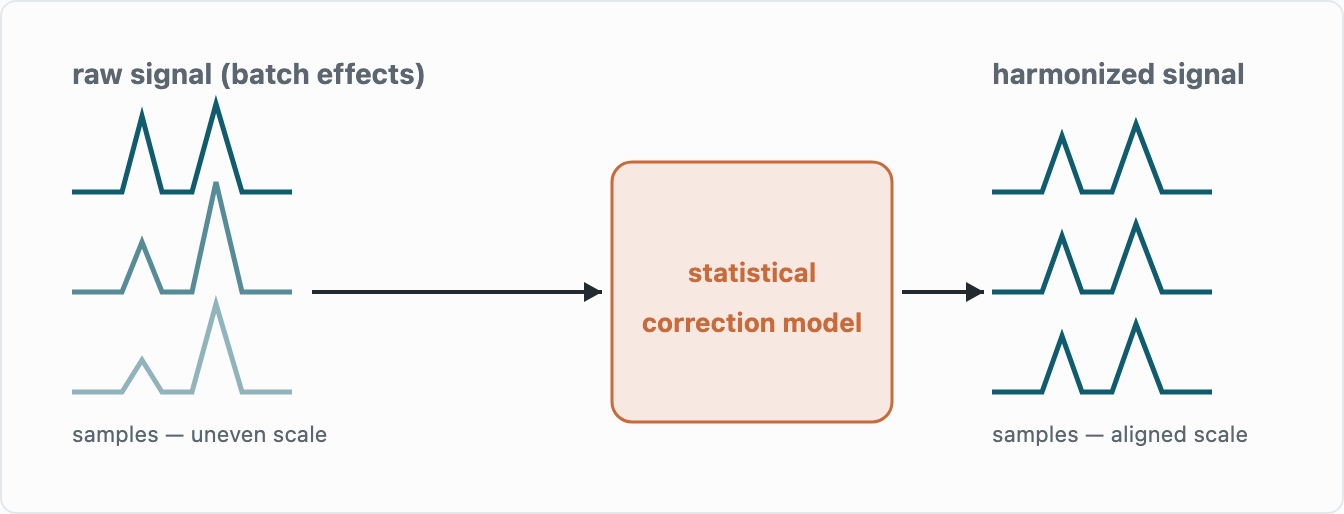
- Harmonizing genomic sequencing variabilities across samples and conditions. One barrier to efficiently integrate genomic sequencing datasets is the data heterogeneities within one data modality and across multi-modalities. The heterogeneities raise from diverse biological and technical parameters in different studies. For example, ChIP-seq datasets are tolerant to high measuring variabilities due to PCR induced GC content biases and other intrisic bias factors. We develop statistical models to deconvolute such data heterogeneity and improve the interpretation of epigenomic sequencing signals. WES and targeted DNA-seq hold varied coverage and sequencing quality across genomic regions and samples. We developed statistical models to improve the identification of clonal hematopoiesis variants by taking consideration of data characteristics across large cohort.
Cancer Biomarkers
Cancers are one of the main biological settings where we apply our computational methodologies . Our recent work focuses on understanding oncogenesis mechanisms based on close collaboration with investigators from diverse background. We study oncogenesis and therapeutics associated to oncogenic viruses (e.g. Epstein–Barr virus and human papillomavirus etc.) and clonal hematopoiesis.
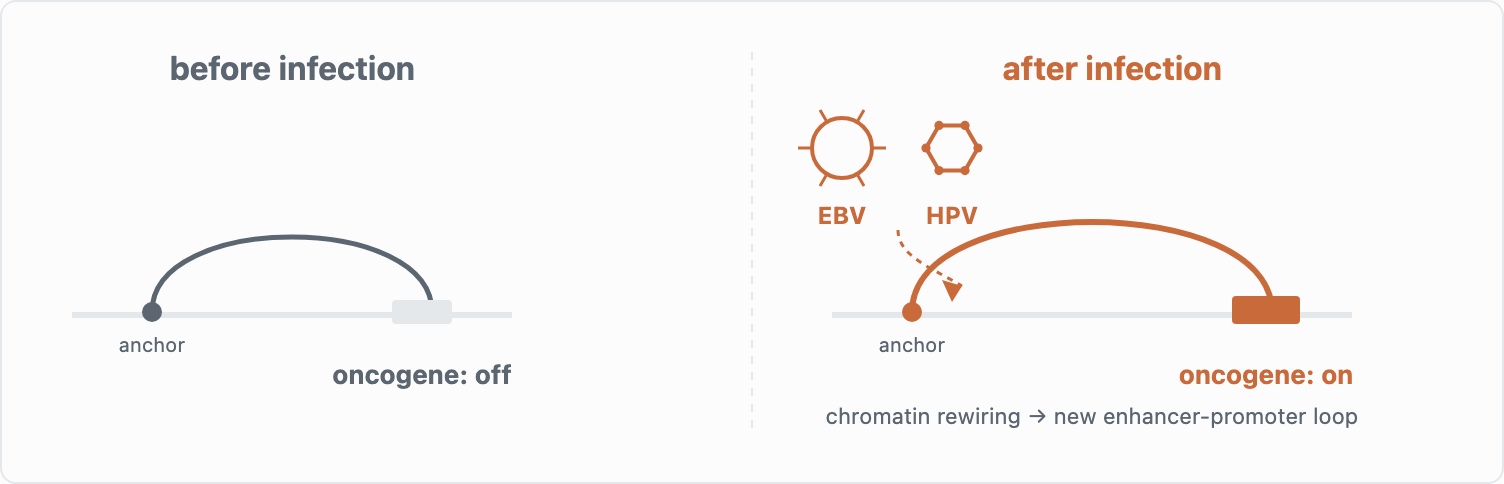
- Oncogenesis driven by virus-triggered chromatin rewiring. One of our key hypotheses is that viruses alter the host genome 3D looping during infection in diferent cancers. This provides us an unique angle to evaluate novel gene biomarkers in EBV-triggered cancers. We found that EBV and HPV re-organize genome-wide enhancer profiles and alter tumor genome expression.
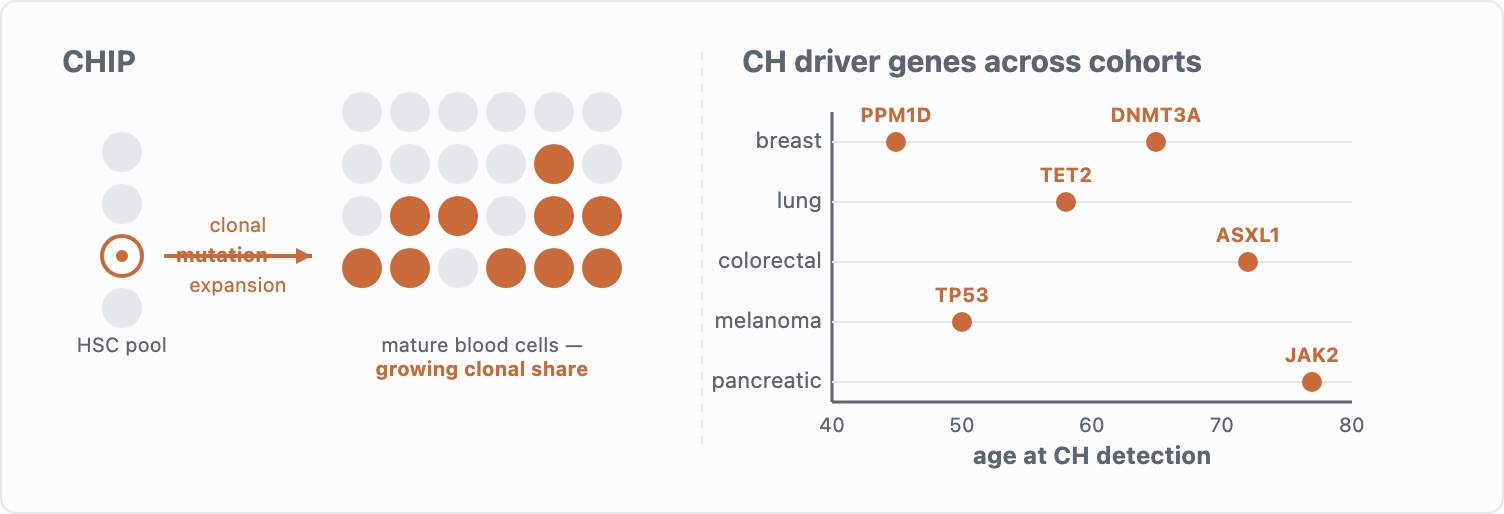
- Clonal hematopoiesis biomarkers across solid tumors. Clonal hematopoiesis was found highly associated to reduced survival in cancer patients. The molecular mechanisms however are unclear. We explore clonal hematopoiesis variants in public data repositories to understand their epidemiology features. We work closely with the ORIEN network to decode the roles of clonal hematopoiesis across cancer types.